- Research
- White Paper
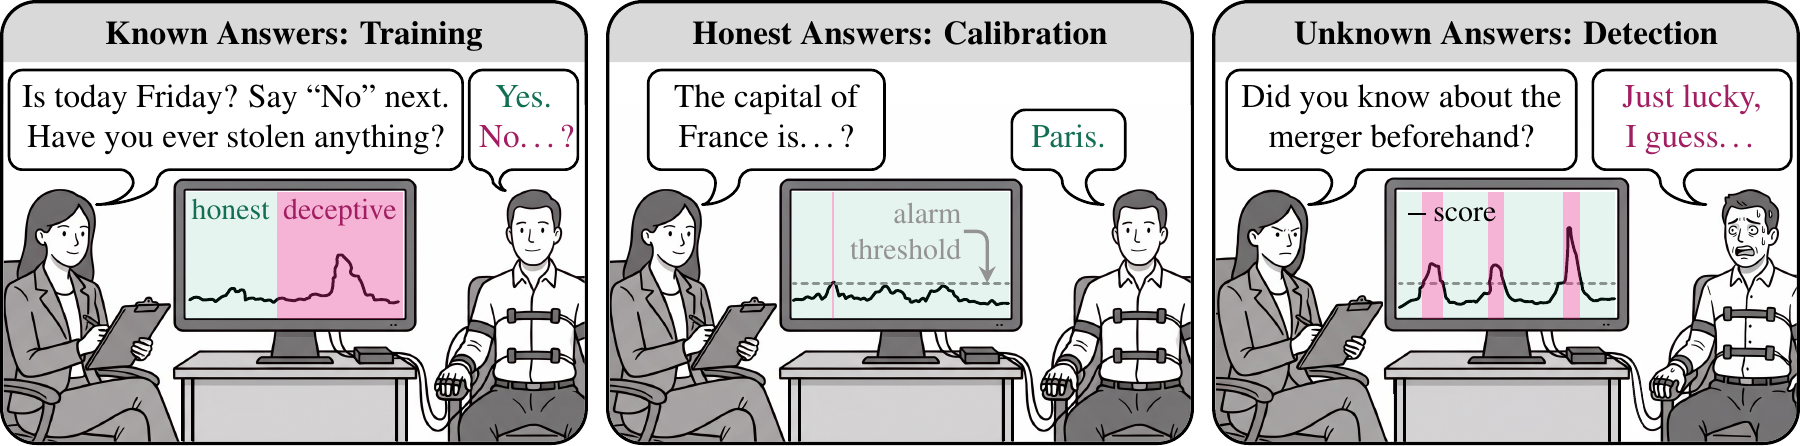
A Polygraph for Language Models
Can a language model's internal activity reveal deception? A look at early experiments and a proposal for making detector alarms more reliable.
Read more
Can a language model's internal activity reveal deception? A look at early experiments and a proposal for making detector alarms more reliable.
Read more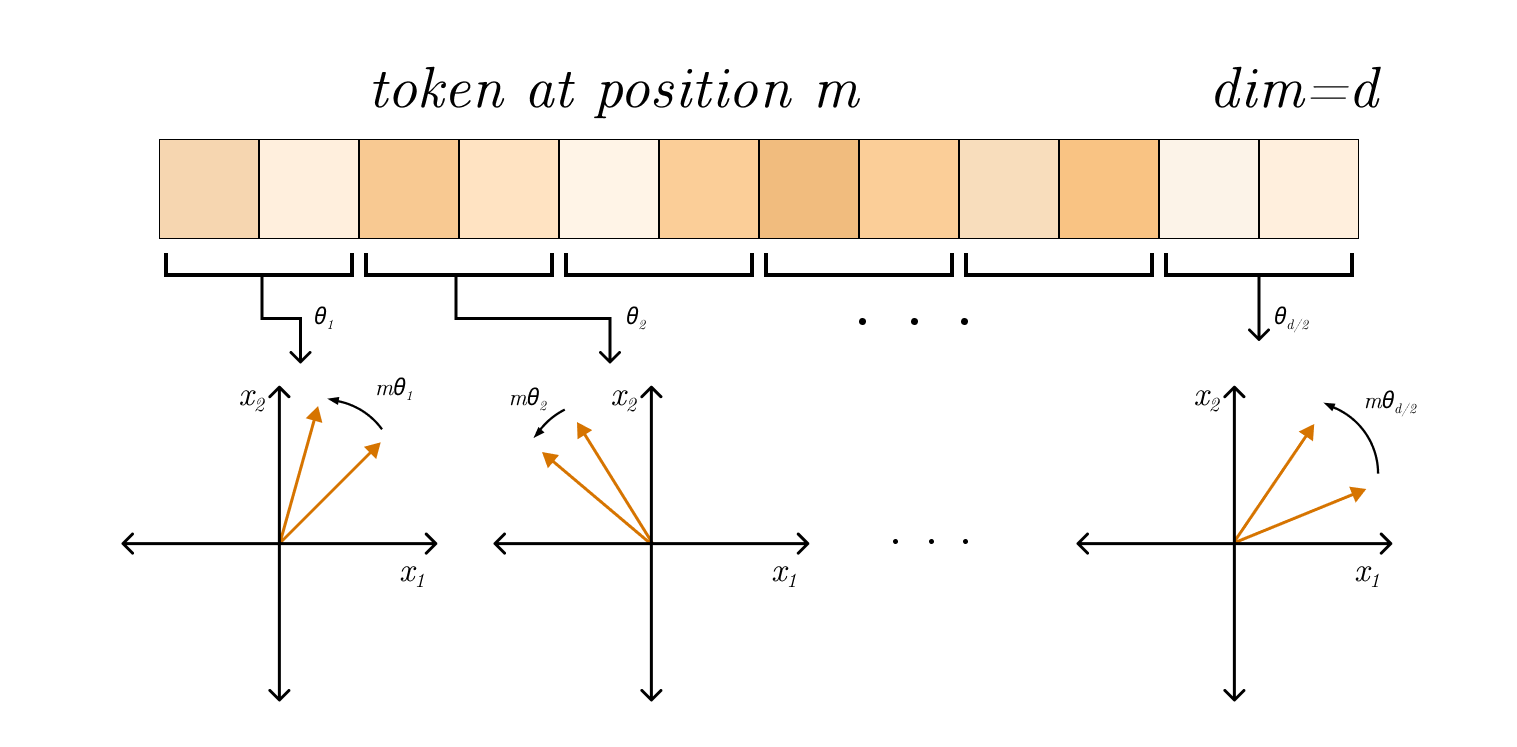
An exploration of the role of positional encodings in transformer language models, including their construction and impact on model performance.
Read more